Text-to-image generation
Metalhead ports text-to-image pipelines from Hugging Face Diffusers, starting with FLUX.2 [klein] of Black Forest Labs, a flow-matching model of 4 billion parameters under the Apache 2.0 license. A diffusers repository holds a pipeline: its model_index.json names the components, each in a subfolder of its own, and create_model builds them all.
using Metalhead, Flux, HuggingFaceTokenizers
using CUDA, cuDNN                   # optional: for a GPU

pipe = create_model("black-forest-labs/FLUX.2-klein-4B"; eltype = BFloat16)
pipe = gpu(pipe)

image = pipe("A photo of a red fox sitting in fresh snow, looking at the camera";
    num_inference_steps = 4)
The pipeline downloads 16 GB of weights, and needs as much memory in BFloat16 (twice that in Float32). FLUX.2 [klein] 4B is distilled to generate an image in 4 steps. Its base version, black-forest-labs/FLUX.2-klein-base-4B, takes about 50 steps with classifier-free guidance (guidance_scale = 4, the default), and is the one to fine-tune.
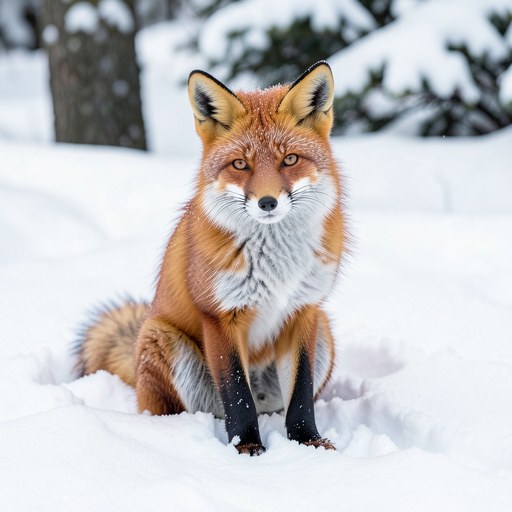
image has size (width, height, 3, batch), with values in [0, 1]. With ImageCore.jl (or Images.jl) loaded, Metalhead.image_matrix makes a vector of images of it, height × width matrices of RGB pixels, and FileIO saves them:
using ImageCore, FileIO

img = only(Metalhead.image_matrix(cpu(image)))
FileIO.save("fox.png", img)  # HuggingFaceTokenizers exports a `save` too
Z-Image-Turbo
Z-Image-Turbo of Alibaba's Tongyi Lab, a model of 6 billion parameters under the Apache 2.0 license, distilled to generate an image in 9 steps without guidance, loads the same way, as a ZImagePipeline:
pipe = gpu(create_model("Tongyi-MAI/Z-Image-Turbo"; eltype = BFloat16))
image = pipe("A photo of a red fox sitting in fresh snow, looking at the camera";
    num_inference_steps = 9, guidance_scale = 0)
Its defaults are those of diffusers' ZImagePipeline, for the base model Z-Image: 50 steps with classifier-free guidance (guidance_scale = 5). The pipeline downloads 33 GB (its transformer is stored in Float32) and holds 21 GB of weights in BFloat16. Its text encoder is the Qwen3 decoder whose hidden states of the second-to-last layer condition the image, one matrix per prompt without the padding; negative_prompt gives the negative prompts of guidance, and cfg_normalization and cfg_truncation limit it as in diffusers.
Options
The keyword arguments of the pipeline are those of diffusers' Flux2KleinPipeline:
heightandwidth(1024 by default, or the size of the first reference image), multiples of 16.image: reference images, to edit (see Image editing below).num_inference_steps, andguidance_scalefor the base checkpoints.latents: the initial noise, of size(width ÷ 16, height ÷ 16, 128, batch). By default it is drawn fromrng(Random.default_rng()), so thatrng = Xoshiro(0)makes an image reproducible. diffusers draws its noise with PyTorch's generator, so the same seed gives different images in the two libraries; the samelatentsgive the same image.output_type = :latentreturns the denoised latents of the autoencoder instead of the image.
A vector of prompts makes a batch of images.
These four images of 1024 × 768 pixels took 1.6 seconds each on an RTX 5090:
using Random: Xoshiro

prompts = ["A watercolor painting of a lighthouse on a rocky cliff at sunset",
    "A macro photograph of dew drops on a spider web at dawn, shallow depth of field",
    "An isometric illustration of a tiny cozy library with warm lights",
    "A bowl of ramen on a wooden table, studio food photography"]
images = [pipe(prompt; width = 1024, height = 768, num_inference_steps = 4,
              rng = Xoshiro(seed)) for (seed, prompt) in enumerate(prompts)]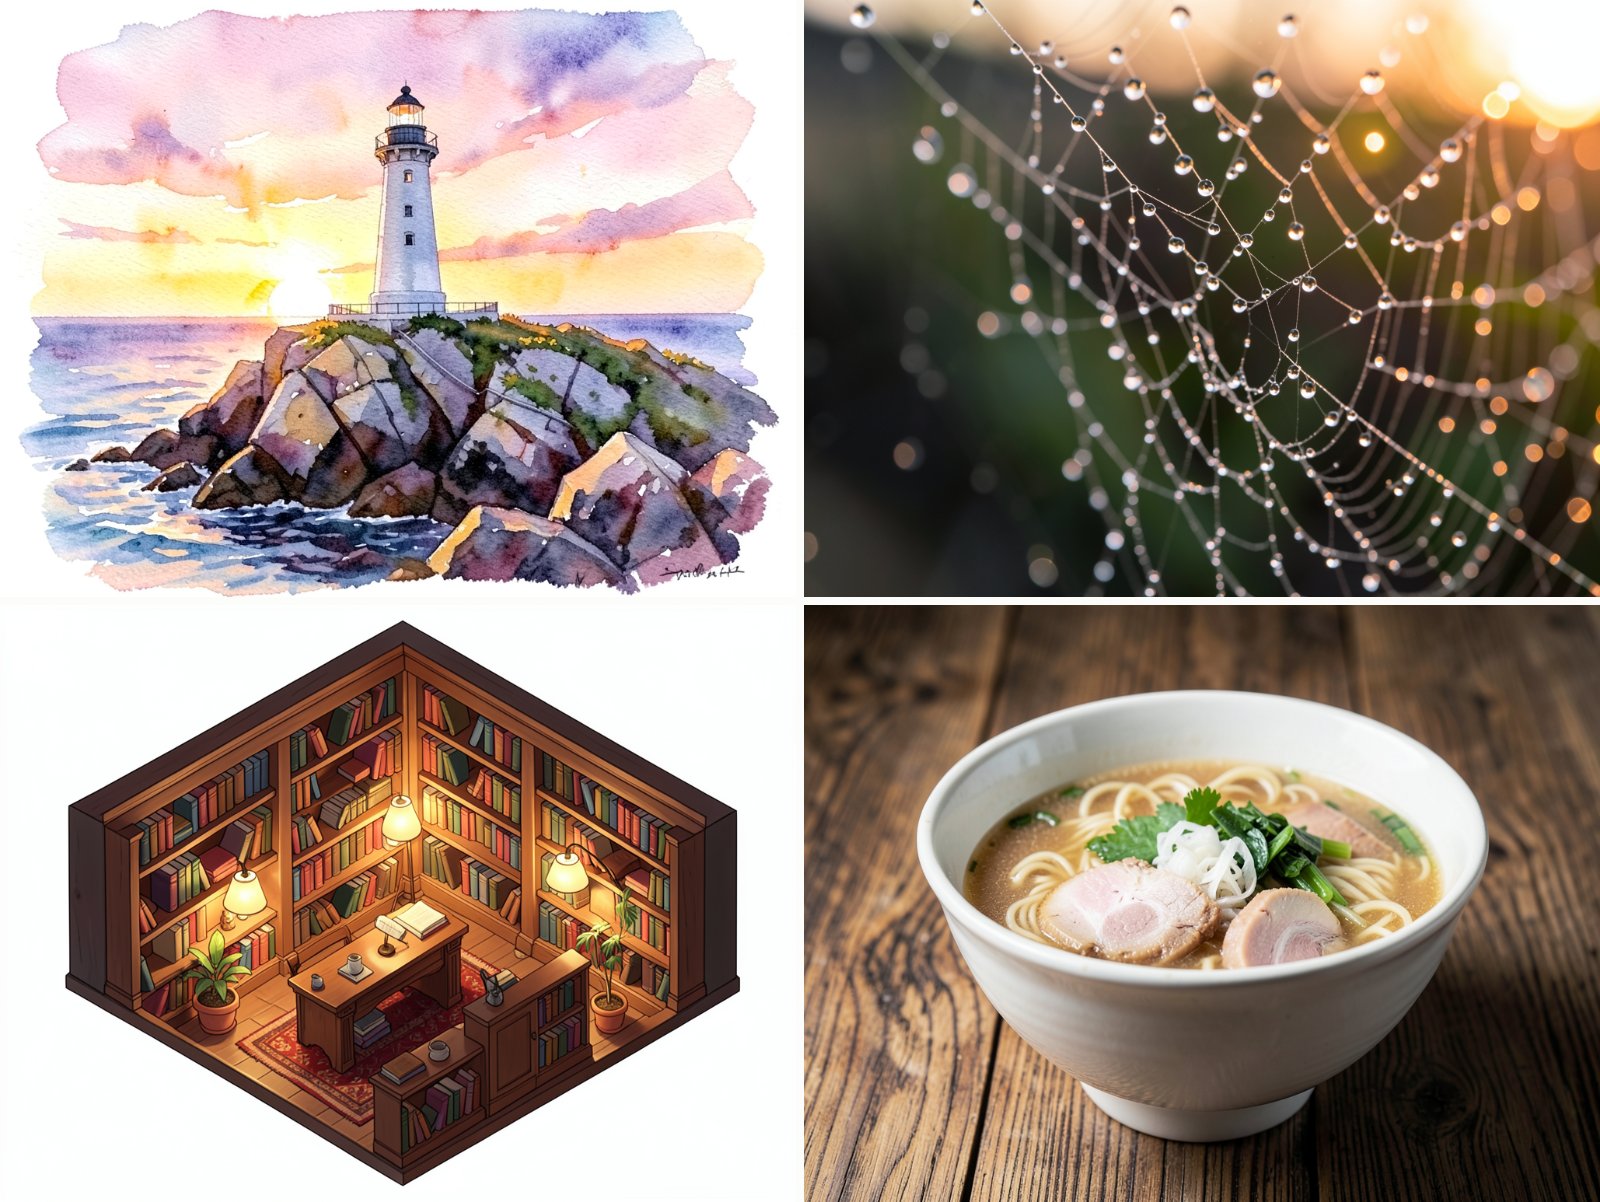
Four prompts, with the seeds 1 to 4, in 4 steps each.
Image editing
Given reference images, image, FLUX.2 [klein] generates the image that the prompt asks of them: the same scene at another time, an object added or restyled, or the subjects of several images put together. A reference image is an image as processors take it (see Metalhead.image_array): an array of size (width, height, channels) of 8-bit values or of reals from 0 to 1, or, with ImageCore loaded, a matrix of colorants as FileIO.load returns it.
using FileIO

fox = load("fox.png")
night = pipe("Make it night, under the northern lights"; image = fox, num_inference_steps = 4)
A vector of images gives several references, which every prompt of a batch takes. The image has the size of the first reference by default; height and width set another. The pipeline prepares each reference as diffusers prepares a PIL image: an image of more than 1024 × 1024 pixels is resized to about that area with Pillow's Lanczos filter (reals are first rounded to 8 bits), its sides are cropped about the centre to multiples of 16, and it is converted to RGB; a side under 64 pixels, or an aspect ratio over 8:1, is an error. The autoencoder encodes each reference into latents, normalised as the latents of the pipeline, and the transformer attends to their tokens along with those of the image it denoises: each reference has a time coordinate of its own in the rotary positions (10 for the first, 20 for the second, ...), the generated image 0. The more reference tokens, the slower each step: one reference of the size of the output about doubles the tokens of the image.
The steps of the pipeline
The prompt is formatted with the chat template of the Qwen3 text encoder, tokenized by the pipeline's tokenizer, and truncated and padded to 512 tokens. The hidden states of three layers of the text encoder are its embeddings:
using Metalhead.Diffusers: encode_prompt

embeds = encode_prompt(pipe, ["A photo of a red fox"])  # 7680 × 512 × 1
The pipeline also takes the embeddings, pipe(embeds; num_inference_steps = 4), which saves encoding the same prompt again and needs no tokenizer. encode_prompt also takes the token indices of prompts tokenized otherwise, with their attention mask.
The components are fields of the pipeline: pipe.text_encoder is a Qwen3 language model (see Language models), pipe.transformer predicts the flow of the latents at each step, pipe.vae decodes the final latents into an image, and pipe.scheduler holds the noise levels of the steps. pipe.vae also encodes the reference images of an edit.
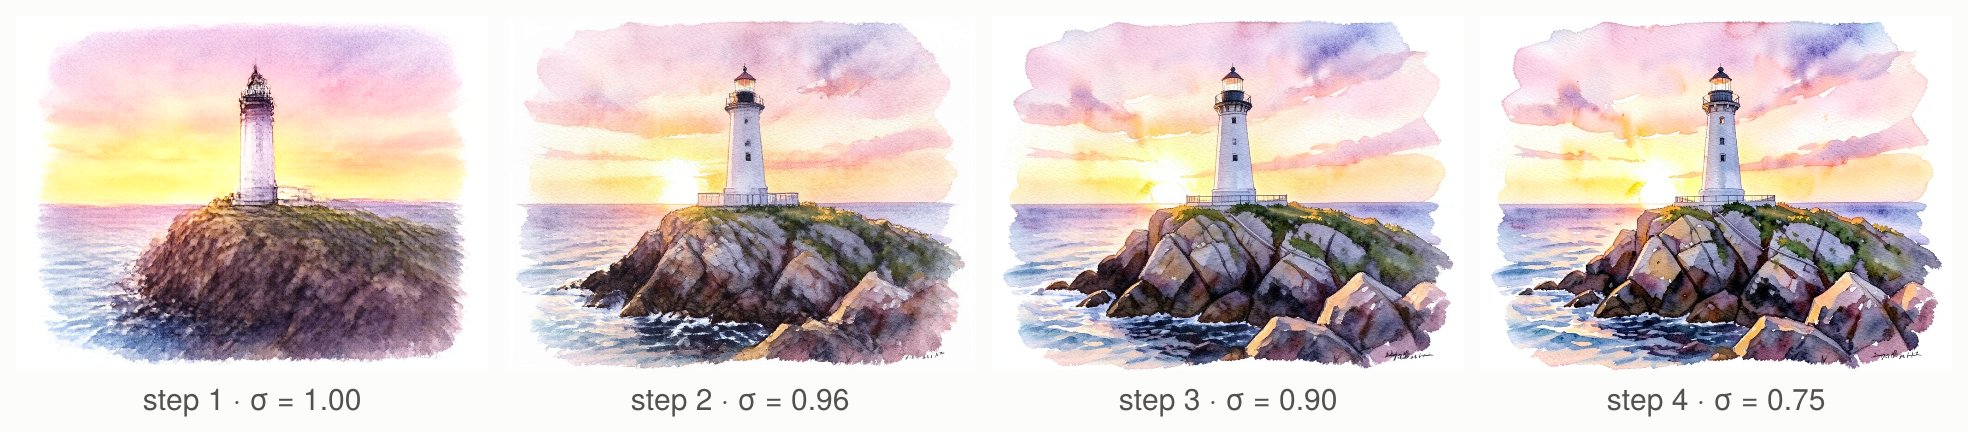
The clean image that the transformer predicts at each of the four steps, from latents at the noise level σ: the first step sets the composition, and the others add detail. The last prediction is the image of the pipeline.
pipe.tokenizer is the tokenizer of the text encoder, HuggingFaceTokenizers.jl's Tokenizer, which gpu and bf16 leave as it is. It loads with the pipeline when HuggingFaceTokenizers is loaded first. Otherwise the pipeline keeps the file of the tokenizer, and loads it once HuggingFaceTokenizers is loaded: a pipeline loaded without it takes embeddings, and takes prompts after using HuggingFaceTokenizers, without loading it again. A pipeline has no processor of its own: it prepares its inputs itself. create_processor(repo; subfolder = "tokenizer") loads the tokenizer alone, as a TextProcessor, and each other component loads on its own with subfolder too:
using Metalhead: Diffusers   # HuggingFaceTokenizers exports an `encode` and a `decode` too

vae = create_model("black-forest-labs/FLUX.2-klein-4B"; subfolder = "vae")
x = rand(Float32, 256, 256, 3, 1) .* 2 .- 1    # an image with values in [-1, 1]
latents = Diffusers.mode(Diffusers.encode(vae, x))   # 32 × 32 × 32 × 1
y = Diffusers.decode(vae, latents)                   # 256 × 256 × 3 × 1
Images are WHCN arrays, as for the vision models. See the docstrings of Metalhead.Diffusers.Flux2KleinPipeline and its components in the API reference for their inputs and outputs.
Precision
The pipeline computes in the element type of its weights, eltype. In BFloat16 (or Float16) the normalisation layers keep their parameters and statistics in Float32 and normalise in Float32, and, as in diffusers, the timestep embeddings and the Euler steps of the scheduler are computed in Float32. On an RTX 5090, FLUX.2 [klein] 4B in BFloat16 takes 15 GB of GPU memory and about 2.5 seconds for an image of 1024 × 1024 pixels in 4 steps.
On the CPU, Float32 is the practical choice: there, matrix products and convolutions in BFloat16 are slow and accumulate in 16 bits.