Working with pre-trained models from Metalhead
Using a model from Metalhead is as simple as selecting a model from the table of available models given on the homepage of the documentation. For example, below we use the pre-trained ResNet-18 model.
using Metalhead

model = ResNet(18; pretrain = true);
ResNet(
Chain(
Chain(
Chain(
Conv((7, 7), 3 => 64, pad=3, stride=2, bias=false), # 9_408 parameters
BatchNorm(64, relu), # 128 parameters, plus 128
MaxPool((3, 3), pad=1, stride=2),
),
Chain(
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 64 => 64, pad=1, bias=false), # 36_864 parameters
BatchNorm(64), # 128 parameters, plus 128
NNlib.relu,
Conv((3, 3), 64 => 64, pad=1, bias=false), # 36_864 parameters
BatchNorm(64), # 128 parameters, plus 128
),
),
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 64 => 64, pad=1, bias=false), # 36_864 parameters
BatchNorm(64), # 128 parameters, plus 128
NNlib.relu,
Conv((3, 3), 64 => 64, pad=1, bias=false), # 36_864 parameters
BatchNorm(64), # 128 parameters, plus 128
),
),
),
Chain(
Parallel(
addact(relu, ...),
Chain(
Conv((1, 1), 64 => 128, stride=2, bias=false), # 8_192 parameters
BatchNorm(128), # 256 parameters, plus 256
),
Chain(
Conv((3, 3), 64 => 128, pad=1, stride=2, bias=false), # 73_728 parameters
BatchNorm(128), # 256 parameters, plus 256
NNlib.relu,
Conv((3, 3), 128 => 128, pad=1, bias=false), # 147_456 parameters
BatchNorm(128), # 256 parameters, plus 256
),
),
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 128 => 128, pad=1, bias=false), # 147_456 parameters
BatchNorm(128), # 256 parameters, plus 256
NNlib.relu,
Conv((3, 3), 128 => 128, pad=1, bias=false), # 147_456 parameters
BatchNorm(128), # 256 parameters, plus 256
),
),
),
Chain(
Parallel(
addact(relu, ...),
Chain(
Conv((1, 1), 128 => 256, stride=2, bias=false), # 32_768 parameters
BatchNorm(256), # 512 parameters, plus 512
),
Chain(
Conv((3, 3), 128 => 256, pad=1, stride=2, bias=false), # 294_912 parameters
BatchNorm(256), # 512 parameters, plus 512
NNlib.relu,
Conv((3, 3), 256 => 256, pad=1, bias=false), # 589_824 parameters
BatchNorm(256), # 512 parameters, plus 512
),
),
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 256 => 256, pad=1, bias=false), # 589_824 parameters
BatchNorm(256), # 512 parameters, plus 512
NNlib.relu,
Conv((3, 3), 256 => 256, pad=1, bias=false), # 589_824 parameters
BatchNorm(256), # 512 parameters, plus 512
),
),
),
Chain(
Parallel(
addact(relu, ...),
Chain(
Conv((1, 1), 256 => 512, stride=2, bias=false), # 131_072 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
),
Chain(
Conv((3, 3), 256 => 512, pad=1, stride=2, bias=false), # 1_179_648 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
NNlib.relu,
Conv((3, 3), 512 => 512, pad=1, bias=false), # 2_359_296 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
),
),
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 512 => 512, pad=1, bias=false), # 2_359_296 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
NNlib.relu,
Conv((3, 3), 512 => 512, pad=1, bias=false), # 2_359_296 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
),
),
),
),
Chain(
AdaptiveMeanPool((1, 1)),
MLUtils.flatten,
Dense(512 => 1000), # 513_000 parameters
),
),
) # Total: 62 trainable arrays, 11_689_512 parameters,
# plus 40 non-trainable, 9_600 parameters, summarysize 44.636 MiB.Using pre-trained models as feature extractors
The backbone and classifier functions do exactly what their names suggest - they are used to extract the backbone and classifier of a model respectively. For example, to extract the backbone of a pre-trained ResNet-18 model:
backbone(model);Chain(
Chain(
Conv((7, 7), 3 => 64, pad=3, stride=2, bias=false), # 9_408 parameters
BatchNorm(64, relu), # 128 parameters, plus 128
MaxPool((3, 3), pad=1, stride=2),
),
Chain(
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 64 => 64, pad=1, bias=false), # 36_864 parameters
BatchNorm(64), # 128 parameters, plus 128
NNlib.relu,
Conv((3, 3), 64 => 64, pad=1, bias=false), # 36_864 parameters
BatchNorm(64), # 128 parameters, plus 128
),
),
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 64 => 64, pad=1, bias=false), # 36_864 parameters
BatchNorm(64), # 128 parameters, plus 128
NNlib.relu,
Conv((3, 3), 64 => 64, pad=1, bias=false), # 36_864 parameters
BatchNorm(64), # 128 parameters, plus 128
),
),
),
Chain(
Parallel(
addact(relu, ...),
Chain(
Conv((1, 1), 64 => 128, stride=2, bias=false), # 8_192 parameters
BatchNorm(128), # 256 parameters, plus 256
),
Chain(
Conv((3, 3), 64 => 128, pad=1, stride=2, bias=false), # 73_728 parameters
BatchNorm(128), # 256 parameters, plus 256
NNlib.relu,
Conv((3, 3), 128 => 128, pad=1, bias=false), # 147_456 parameters
BatchNorm(128), # 256 parameters, plus 256
),
),
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 128 => 128, pad=1, bias=false), # 147_456 parameters
BatchNorm(128), # 256 parameters, plus 256
NNlib.relu,
Conv((3, 3), 128 => 128, pad=1, bias=false), # 147_456 parameters
BatchNorm(128), # 256 parameters, plus 256
),
),
),
Chain(
Parallel(
addact(relu, ...),
Chain(
Conv((1, 1), 128 => 256, stride=2, bias=false), # 32_768 parameters
BatchNorm(256), # 512 parameters, plus 512
),
Chain(
Conv((3, 3), 128 => 256, pad=1, stride=2, bias=false), # 294_912 parameters
BatchNorm(256), # 512 parameters, plus 512
NNlib.relu,
Conv((3, 3), 256 => 256, pad=1, bias=false), # 589_824 parameters
BatchNorm(256), # 512 parameters, plus 512
),
),
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 256 => 256, pad=1, bias=false), # 589_824 parameters
BatchNorm(256), # 512 parameters, plus 512
NNlib.relu,
Conv((3, 3), 256 => 256, pad=1, bias=false), # 589_824 parameters
BatchNorm(256), # 512 parameters, plus 512
),
),
),
Chain(
Parallel(
addact(relu, ...),
Chain(
Conv((1, 1), 256 => 512, stride=2, bias=false), # 131_072 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
),
Chain(
Conv((3, 3), 256 => 512, pad=1, stride=2, bias=false), # 1_179_648 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
NNlib.relu,
Conv((3, 3), 512 => 512, pad=1, bias=false), # 2_359_296 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
),
),
Parallel(
addact(relu, ...),
identity,
Chain(
Conv((3, 3), 512 => 512, pad=1, bias=false), # 2_359_296 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
NNlib.relu,
Conv((3, 3), 512 => 512, pad=1, bias=false), # 2_359_296 parameters
BatchNorm(512), # 1_024 parameters, plus 1_024
),
),
),
) # Total: 60 trainable arrays, 11_176_512 parameters,
# plus 40 non-trainable, 9_600 parameters, summarysize 42.679 MiB.The backbone function could also be useful for people looking to just use specific sections of the model for transfer learning. The function returns a Chain of the layers of the model, so you can easily index into it to get the layers you want. For example, to get the first five layers of a pre-trained ResNet model, you can just write backbone(model)[1:5].
Training
Now, we can use this model with Flux like any other model. First, let's check the accuracy on a test image from ImageNet.
using Images

# test image
img = Images.load(download("https://cdn.pixabay.com/photo/2015/05/07/11/02/guitar-756326_960_720.jpg"));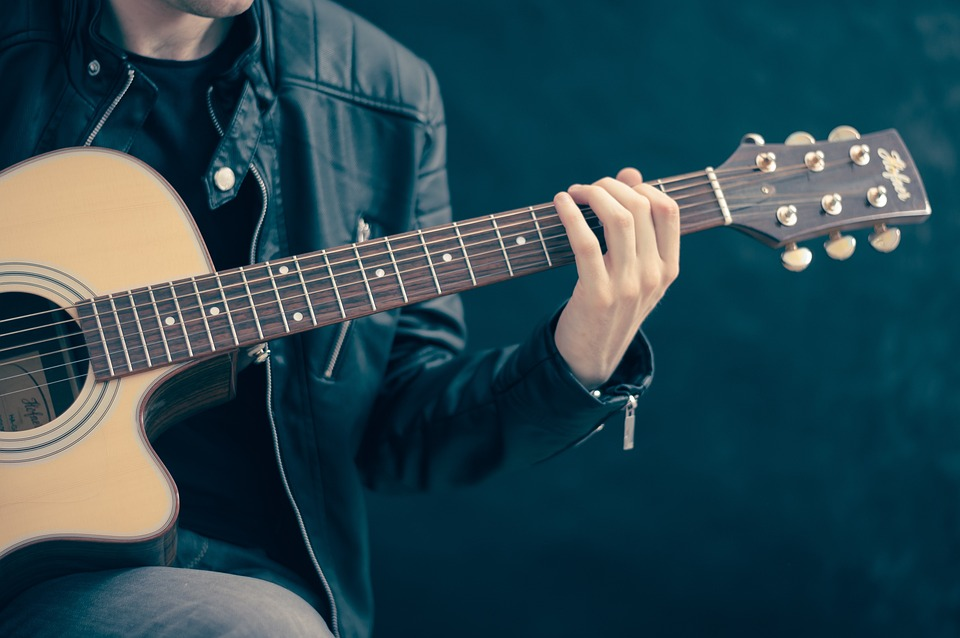
We'll use the popular DataAugmentation.jl library to crop our input image, convert it to a plain array, and normalize the pixels. Flux expects arrays in the width × height × channels × batch (WHCN) layout; ImageToTensor already returns width × height × channels, so we only need to add a batch dimension.
using DataAugmentation
using Flux
using Flux: onecold

DATA_MEAN = (0.485, 0.456, 0.406)
DATA_STD = (0.229, 0.224, 0.225)

augmentations = CenterCrop((224, 224)) |>
                ImageToTensor() |>
                Normalize(DATA_MEAN, DATA_STD)

data = apply(augmentations, Image(img)) |> itemdata  # width × height × channels

# ImageNet labels
labels = readlines(download("https://raw.githubusercontent.com/pytorch/hub/master/imagenet_classes.txt"))

println(onecold(model(Flux.unsqueeze(data, 4)), labels))
["acoustic guitar"]If you convert images to arrays yourself, keep the layout in mind: for an image img of size height × width, channelview(img) has size channels × height × width, so permutedims(channelview(img), (3, 2, 1)) gives the width × height × channels array that Flux expects. Skipping the permutation silently feeds the model a transposed image.
That is fairly accurate! Below, we train the model on some randomly generated data:
using Flux: onehotbatch
using Flux.Losses: logitcrossentropy

batchsize = 1
data = [(rand(Float32, 224, 224, 3, batchsize), onehotbatch(rand(1:1000, batchsize), 1:1000))
        for _ in 1:3]
loss(m, x, y) = logitcrossentropy(m(x), y)
opt_state = Flux.setup(Adam(), model)  # initialise this optimiser's state
Flux.train!(loss, model, data, opt_state)
If you need more control over the training loop, you can write it yourself using Flux.gradient and Flux.update!:
for (x, y) in data
    grads = Flux.gradient(m -> loss(m, x, y), model)
    Flux.update!(opt_state, model, grads[1])
end